High-Throughput LLM Inference & Training: A Deep Dive into vLLM
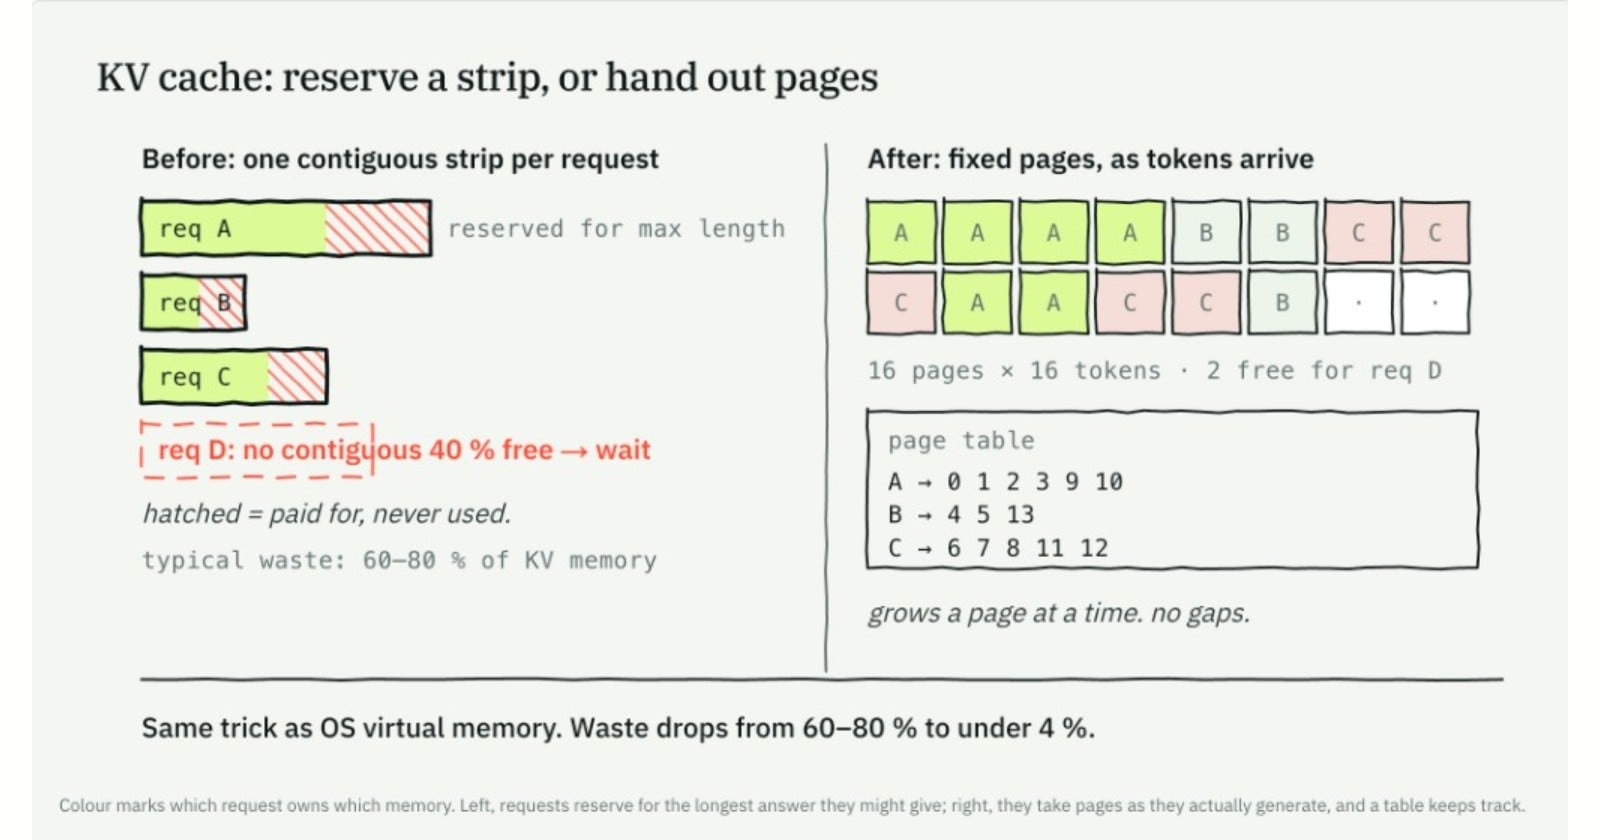
A technical deep dive into vLLM: PagedAttention, continuous batching, chunked prefill, CUDA graphs, and empirical benchmarks from gft-studio across GRPO rollout phases and inference serving on NVIDIA H100 and H200.
Sep 21, 202613 min read7